Author & Editorial Review
Arkadii Misiurov
SEO strategy and technical search team
Lemon SEO's editorial team writes evidence-led search guidance for businesses that need practical SEO, AI search, content, and measurement workflows.
Services
AI-search visibility is now a crawl-policy conversation as much as a content conversation. The mistake is treating every crawler setting as if it were a ranking lever. Google-Extended is worth reviewing because Google's common crawler documentation was updated on July 14, 2026, but the practical takeaway is specific: Google-Extended is an AI-product control, not a switch for Google Search inclusion or rankings.
That distinction matters when a founder asks, "Should we block AI crawlers?" Start with product scope. One rule might protect commercial content from a training or grounding use case. Another might accidentally block a crawler needed for organic visibility. Map the control before changing the file.
For Lemon SEO clients, we put this kind of decision inside an AI search services or technical SEO review, because crawler rules touch search visibility, model-use policy, developer release process, and content governance at the same time.
Google documents Google-Extended as a standalone product token. It does not have a separate HTTP request user agent string; crawling is done with existing Google user agent strings, while the robots.txt user-agent token is used in a control capacity. In plain English: you may not see a neat, separate "Google-Extended" crawler in raw logs the way a non-specialist expects.
The affected use case is narrower than many teams assume. Google says the token lets publishers manage whether content Google crawls from their sites may be used for future Gemini model training and for grounding in Gemini Apps and Grounding with Google Search on Vertex AI. Google also states that Google-Extended does not affect Search inclusion and is not used as a Google Search ranking signal.
So the decision is not "AI visibility versus no AI visibility." It is closer to this:
That is a policy decision. It should be made deliberately, documented, and tested.
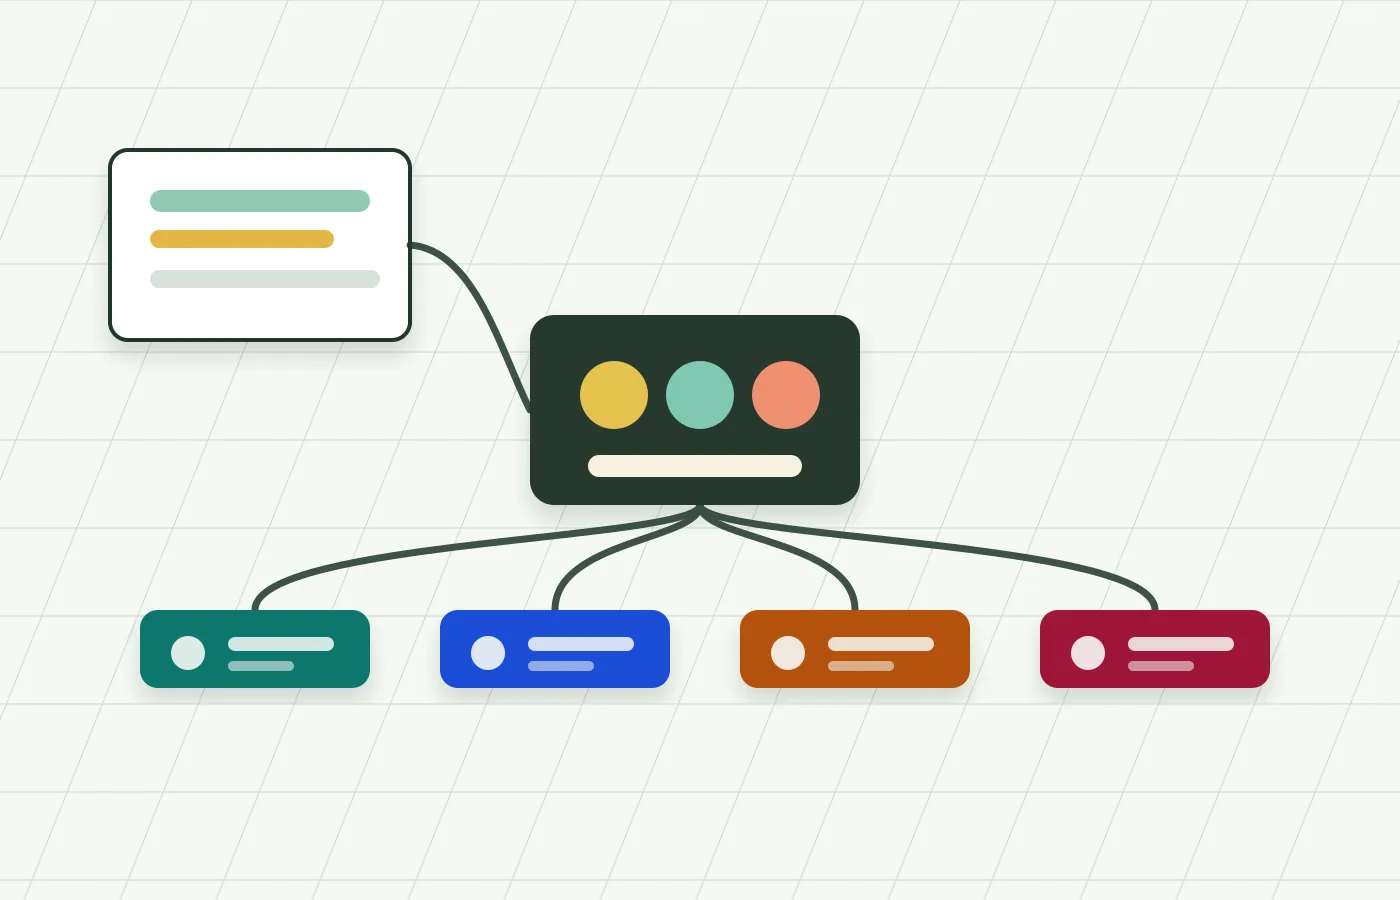
Start by separating crawler classes. Google common crawlers, such as Googlebot, are used for products including Google Search and always respect robots.txt rules for automatic crawls. Special-case crawlers may have product-specific behavior; Google's overview uses AdsBot as an example of a crawler that can ignore the global robots.txt user agent with the ad publisher's permission. Google-CloudVertexBot is different again: Google documents it as affecting crawls requested by site owners for Vertex AI Agents, with no effect on Google Search or other products.
This is why a copied blocklist is a weak control. It may mix search crawlers, AI-product tokens, ad crawlers, owner-requested fetches, CDN bot rules, and non-Google AI bots without any product owner or measurement plan.
A better inventory looks like this:
The point is not to allow everything. It is to stop guessing.
Robots.txt is a text file containing rules about which crawlers may access which parts of a site. Google says it must be placed in the top-level directory of a site on a supported protocol. It also says the rules apply only to the host, protocol, and port where the file is hosted.
That scope creates common failure modes:
Google supports fields such as user-agent, allow, disallow, and sitemap; unsupported assumptions like using crawl-delay for Google should not be treated as a release control. Test important rules with the same discipline you would use for canonicals, redirects, or indexability.
| Control class | Primary question | Safe release check |
|---|---|---|
| Google Search crawl | Can important pages stay crawlable, indexable, and snippet-eligible? | Review robots.txt, CDN rules, logs, and Search Console after release. |
| Google-Extended | Should crawled content be available for Gemini training or grounding use? | Confirm the token is intentional and does not block Googlebot. |
| Owner-requested fetches | Did a product owner request the crawl for a specific integration? | Confirm the product, owner, and path scope before allowing or blocking. |
| Non-Google AI bots | Which external crawler is being controlled, and why? | Check that vendor-specific rules do not mask Search crawl failures. |
A crawler policy change should move through a narrow release workflow. The minimum version is short enough to run in a normal technical SEO sprint:
A simple example: a SaaS documentation site may decide to disallow Google-Extended for private commercial reasons while keeping Googlebot fully allowed on public docs, product pages, and comparison pages. That is a coherent policy if the team confirms that Googlebot still crawls important pages, canonical tags remain stable, and Search Console does not show new crawl or indexing problems. It would not be coherent to claim the Google-Extended rule caused higher rankings, lower rankings, or AI Overview eligibility changes. The source-backed claim is narrower than that.
Google's AI features guidance is direct: the best practices for SEO remain relevant for AI features in Google Search, and there are no additional requirements or special optimizations needed to appear in AI Overviews or AI Mode. Google also says a page must be indexed and eligible to be shown in Google Search with a snippet to be eligible as a supporting link.
That means crawler policy should not distract from the basics:
This is where SEO services, web development services, and AI-search work overlap. A robots.txt decision without page quality, internal linking, rendering, and measurement is only a policy fragment.
Crawler access is not a substitute for useful content. Google's helpful-content guidance centers on reliable, people-first material rather than content created only to gain rankings. It also says AI-generated content is not against Google Search guidelines when it is not produced primarily to manipulate rankings, and that AI or automation disclosures can be useful when readers would reasonably ask how content was created.
A good policy does not hide thin content behind bot rules. It makes the best public content easier for users and search systems to understand, while putting justified boundaries around content use cases the business does not want.
Before approving an AI-crawler policy change:
There is no universal answer to "should we block AI crawlers?" The defensible answer depends on what the crawler controls, which content is affected, whether Search visibility must be preserved, and whether the business has a real reason to restrict model-related use. Google-Extended is a good example because its scope is documented clearly enough to support a precise decision: it can govern named Gemini-related training and grounding uses, but it is not a Google Search ranking lever.
If your team is unsure which crawler rules are active, which pages are exposed, or whether a planned block could reduce organic visibility, start with a constrained audit. Lemon SEO can review crawler policy, logs, Search Console signals, and page-level SEO dependencies through AI search services. To scope the risk on your site, Request a free audit.
Turn the findings into a practical growth plan with Lemon SEO.